
PD4ML v4.2.0 snapshot: the v42 layout engine


The first development snapshot of PD4ML v4.2.0 is available. Its main addition is a second HTML/CSS layout engine, v42, which works alongside the existing v40 engine and is the basis for most of the new features. v40 stays the default, so applications that don’t opt in keep their current output.

What’s in the snapshot

  • The v42 layout engine: a tolerant HTML5 parser, Flexbox, CSS Grid, multi-column layout continued across pages, vertical writing modes and media queries level 4. Its layout is checked against Chrome’s print output. Select it with useHtmlRenderer(Constants.LayoutEngine.v42) before readHTML().
  • CSS @page rules: page size and margins, first, left, right and blank pages, named pages, and the 16 page-margin boxes with page counters (v42).
  • The same output on every machine: v42 uses only the configured font set, @font-face rules and the fonts bundled with PD4ML, never the fonts installed on the host.
  • A DOM API: read and change the parsed document between readHTML() and the output: query it with CSS selectors, edit text, attributes and styles, and find out where each element is laid out (DMS and UA editions, v42).
  • Word output from the same layout: with v42, DOCX and RTF follow the layout of the PDF, and with the UA edition the Word documents are accessible too.
  • Both engines: CSS gradients, color emoji, .eml and .mht input (DMS and UA editions), smaller PDF files by default, watermarks in DOCX and RTF, and restricted resource loading for untrusted HTML.

The full list, with links to the manual sections and usage examples, is on the documentation page What Is New in PD4ML v4.2.0.

Getting it

Download the latest build from the Downloads page, or use 4.2.0-SNAPSHOT from the PD4ML Maven repository (see Using PD4ML with Apache Maven).

This is a development snapshot: features and details can still change before the release, and it hasn’t been tested to release level, so try it before you deploy. We’d like to hear how your documents come out with the v42 engine. Please report problems and differences from the browser on the support forum.
Beyond Java: PD4ML v4 Comes to Python, PHP, .NET, Node.js and Ruby


PD4ML v4 is a Java library (well, the .NET edition of PD4ML is still at v3, with the port of v4 pending), but the documents it produces are needed everywhere: in Django and Flask apps, PHP shops, ASP.NET services, Node.js backends and Rails applications. From today, all of them can use PD4ML v4 directly. Five new integrations bring its complete API – the same one the Java manual describes – to Python, PHP, .NET, Node.js and Ruby.

One install, no Java code

Each integration installs with the language’s own package manager:

  • Python: pip install pd4ml (PyPI)
  • PHP: composer require pd4ml/pd4ml-php (Packagist)
  • Node.js: npm install pd4ml (npm)
  • Ruby: gem install pd4ml (RubyGems)
  • .NET: the Pd4ml.Net NuGet package from pd4ml.com/net

Then one command – pd4ml install (in PHP projects vendor/bin/pd4ml install) – downloads the most recent PD4ML release and the Bouncy Castle libraries it needs for signing from the PD4ML Maven repository, checking every file against its published checksum. The Python, Node.js and Ruby integrations even do that on their own at first use. The only other requirement is a Java runtime (8 or later) on the machine.

The same API, in your language

The familiar PD4ML calls read naturally in each language. A PDF from an HTML string in Python:

import pd4ml

pd = pd4ml.PD4ML()
pd.setPageSize(pd4ml.PageSize.A4)
pd.read_html_string("<h1>Hello, PDF</h1><p>Generated with <b>PD4ML</b>.</p>")
pd.writePDF("hello.pdf")

The same in PHP:

use Pd4ml\PD4ML;
use Pd4ml\Java;

$pd = new PD4ML();
$pd->setPageSize(Java::PageSize()->A4);
$pd->readHtmlString('<h1>Hello, PDF</h1><p>Generated with <b>PD4ML</b>.</p>');
$pd->writePDF('hello.pdf');

In C#:

using Pd4mlNet;

var pd = new PD4ML();
pd.SetPageSize(PageSize.A4);
pd.ReadHtmlString("<h1>Hello, PDF</h1><p>Generated with <b>PD4ML</b>.</p>");
pd.WritePDF("hello.pdf");

In Node.js:

const { PD4ML, PageSize } = require('pd4ml');

const pd = new PD4ML();
pd.setPageSize(PageSize.A4);
pd.readHtmlString('<h1>Hello, PDF</h1><p>Generated with <b>PD4ML</b>.</p>');
pd.writePDF('hello.pdf');

And in Ruby:

require 'pd4ml'

pd = Pd4ml::PD4ML.new
pd.set_page_size(Pd4ml::PageSize::A4)
pd.read_html_string('<h1>Hello, PDF</h1><p>Generated with <b>PD4ML</b>.</p>')
pd.write_pdf('hello.pdf')

Beyond “hello world”, every feature of PD4ML is there: PDF/A and PDF/UA, ZUGFeRD and Factur-X invoices, DOCX and RTF output, page images, headers and footers with page numbers, watermarks, bookmarks, fonts, encryption and permissions, and the PDF toolkit for merging, overlaying and signing existing documents. Each integration also adds what makes it feel at home: file paths, byte strings and streams instead of Java I/O, the language’s own error handling, callbacks as progress listeners – and a command line tool for quick conversions.

A note on .NET

PD4ML for .NET is a temporary solution. Like the other integrations, it runs the Java PD4ML in a small bridge process next to your application – so it needs a Java runtime, but in return gives .NET applications today’s PD4ML: the same features, the same output and the same releases as the Java library. The native PD4ML.NET, a fully managed port, is based on PD4ML v3; its port of v4 is pending, and when it is ready, it will take this package’s place. Until then, Pd4ml.Net is the way to use PD4ML v4 from C# and the other .NET languages, with typed classes for the whole API.

Documentation

Every integration comes with a user guide: installation, how it works, use cases with runnable code for the common tasks, tips, troubleshooting and an API reference. They are in the new Integrations section of the PD4ML documentation:

For PD4ML itself – layout, page formats, fonts, standards – the guides refer to the PD4ML Programmer’s Manual, whose API they all share. The sources of the PHP, Node.js and Ruby packages are on GitHub: pd4ml-php, pd4ml-node, pd4ml-ruby.

Availability

All five integrations are available now. They work with the current PD4ML release, and they pick up new PD4ML releases with a single pd4ml install. As with PD4ML for Java, an evaluation runs without a license, with watermarked output; your existing PD4ML license applies to them as well.

Questions, or a framework you would like to see covered? Let us know – we’d like to hear how you use PD4ML from your language.

Multicolumn layout is back in PD4ML


Newsletters, catalogs, glossaries and price lists read better in narrow columns than in lines that run across the whole page. PD4ML v3 users have long relied on generateMulticolumn() for exactly that – and with PD4ML v4.0.24 and v4.1.2 the feature is back, rebuilt for the v4 rendering pipeline.

One call

PD4ML pd4ml = new PD4ML();
pd4ml.generateMulticolumn(2, 8, true);   // 2 columns per page, 8 mm gap
pd4ml.readHTML(new URL("file:newsletter.html"));
pd4ml.writePDF(fos);

The call is the same as in v3, so existing v3 code carries over unchanged.

How it works

  • The document is laid out to the width of a column, and the columns of each page are filled one after another. Every page break – the ones the layout finds as well as <pd4ml:page.break> – moves on to the next column; after the last column a new page starts.
  • <pd4ml:page.break multicolumn="true"/> starts a new page right away, for example for an appendix or a new chapter.
  • Page headers, footers, backgrounds and watermarks belong to the page, not to a column: they span all columns, and $[page] / $[total] count pages, not columns.
  • Footnotes are placed at the bottom of the column that refers to them; links and bookmarks point to the right column.
  • Any page format works: three columns on landscape A4 are one setPageSize(PageSize.A4.rotate()) away.

See it in action

Two new runnable examples in the pd4ml-examples repository, each with its HTML source and the resulting PDF:

Documentation

Availability

Multicolumn layout is part of the PD4ML v4.0.24 and v4.1.2 snapshot builds, already available for download and from the PD4ML Maven repository. It applies to PDF output; as in v3, it is ignored together with adjustHtmlWidth() and fitPageVertically().

Questions or a layout that doesn’t come out as expected? Let us know – we’d like to see your multicolumn documents.

Static Analysis & Code Quality Hardening


v4.0.23fx2 / v4.1.1 releases complete a comprehensive static-analysis review of the entire codebase using SpotBugs, an industry-standard Java code-quality and security scanner. Findings dropped from 1,457 to 562 — a 61% reduction — verified across six independent re-scan passes.

Reliability & correctness

  • Resolved a thread-safety race condition in application configuration loading that could, under concurrent use, expose a partially-initialized internal object.
  • Corrected multiple rounding/truncation defects in page-layout calculations (table, flex, and image positioning) that could cause sub-pixel inaccuracies.
  • Fixed an off-by-one detection bug affecting web font format recognition.
  • Corrected several string-comparison bugs that could cause incorrect matching under edge-case input.
  • Closed gaps where errors were being silently discarded instead of logged.

Code quality & maintainability

  • Brought internal data-sorting components in line with Java serialization best practices.
  • Modernized number-object construction throughout the codebase (~144 call sites) to current Java standards, eliminating deprecated API usage.
  • Removed 12 confirmed-dead code paths (fields written but never read), reducing attack surface and maintenance burden.
  • Addressed switch-statement completeness gaps that could mask unhandled cases.
  • General conformance cleanup across best-practice, internationalization, and multi-threading-safety categories.

Governance

  • Every remaining finding not fixed outright was individually reviewed; those intentionally left in place are documented in-code with the reasoning, and are now machine-verifiable via standard suppression annotations rather than relying on comments alone — confirmed effective through re-scanning.
  • No findings were dismissed without review; the sweep covered the tool’s full default rule set.

Net result: a measurably lower defect-density codebase with an auditable, reproducible verification trail — no open finding was closed without either a fix or a documented, reviewed rationale.

New general-purpose PDF manipulation APIs


We’re excited to announce five major new packages in PD4ML, extending it well beyond HTML-to-PDF conversion into general-purpose PDF manipulation.

Sign PDFs, the right way. com.pd4ml.pdf.sign brings digital signatures to PD4ML: PKCS#12 files, PKCS#11 hardware tokens, HSMs, even cloud KMS providers. Add RFC 3161 timestamps, certify documents with DocMDP, and go long-term with PAdES-LT/LTV so your signatures stay verifiable for years.

Combine documents effortlessly. com.pd4ml.pdf.merge lets you pick page ranges from two or more PDFs and merge them into a single, clean output — accessibility tagging included, so screen readers keep working across the merged result.

Shrink bloated PDFs. com.pd4ml.pdf.optimizer sweeps away unreferenced objects, deduplicates identical content, and collapses years of incremental-update history into one tidy file.

Round-trip comments and form data. com.pd4ml.pdf.xfdf speaks XFDF (ISO 19444-1) — export annotations and form values out of a PDF, or import a reviewer’s markup back in, interoperating cleanly with other PDF tools.

And underneath it all: com.pd4ml.pdf.cos — the low-level PDF object model, parser, and writer that powers every feature above, also usable directly for your own structural edits and COS-path queries.

Every feature ships with a ready-to-run command-line tool (CosCli, PdfSignCli, Pd4MergeCli, Pd4OptimizeCli, Pd4XfdfCli) — no code required.

New in PD4ML v4.1.0


In version PD4ML v4.1.0 the product has been improved in the following areas:

  • Security – AES-128 is used as the default encryption method
     
  • PDF Standards conformance – allows you to specify the required PDF standard compliance. See: Compliance with PDF standards
     
  • XML invoicing support – simplifies the creation of XML invoices that comply with the hybrid electronic invoicing standards. See: ZUGFeRD and Factur-X PDF Invoices generation
     
  • Error policies – You can now specify how errors are handled: either ignore them or throw an exception at the caller level. Four policies can be defined: RELAXED (default; ignore all errors where possible), NORMAL (throw an exception on error), PEDANTIC (treat potential PDF/A and PDF/UA incompatibility as an error and throw an exception), and STRICT (throw an exception even on warnings, such as if the specified font cannot display some text and a fallback font is required).
     

Compliance with PDF standards


PD4ML v4.1.0 introduces a new API method, pd4ml.writePDF(OutputStream, PdfSpec), which allows you to specify the required PDF standard compliance level.

Available options:

  • PDF1.4 – PdfSpec.PDF_1_4 – Acrobat 5
  • PDF1.5 – PdfSpec.PDF_1_5 – Acrobat 6
  • PDF1.6 – PdfSpec.PDF_1_6 – Acrobat 7
  • PDF1.7 – PdfSpec.PDF_1_7 – Acrobat 8 / ISO 3200-1
  • PDF1.7ext1 – PdfSpec.PDF_1_7_1
  • PDF1.7ext2 – PdfSpec.PDF_1_7_2
  • PDF1.7ext3 – PdfSpec.PDF_1_7_3 – Acrobat 9
  • PDF1.7ext4 – PdfSpec.PDF_1_7_4
  • PDF1.7ext5 – PdfSpec.PDF_1_7_5
  • PDF1.7ext6 – PdfSpec.PDF_1_7_6
  • PDF1.7ext7 – PdfSpec.PDF_1_7_7
  • PDF1.7ext8 – PdfSpec.PDF_1_7_8 – Acrobat X
  • PDF1.7ext9 – PdfSpec.PDF_1_7_9
  • PDF1.7ext10 – PdfSpec.PDF_1_7_10
  • PDF1.7ext11 – PdfSpec.PDF_1_7_11 – Acrobat XI
  • PDF2.0 – PdfSpec.PDF_2_0

The PdfSpec parameter can be combined with one of PDF/A modifiers

  • PDF/A-1a:2005 – PdfSpec.PDFA_1A
  • PDF/A-1b:2005 – PdfSpec.PDFA_1B
  • PDF/A-2a – PdfSpec.PDFA_2A
  • PDF/A-2b – PdfSpec.PDFA_2B
  • PDF/A-2u – PdfSpec.PDFA_2U
  • PDF/A-3a – PdfSpec.PDFA_3A
  • PDF/A-3b – PdfSpec.PDFA_3B
  • PDF/A-3u – PdfSpec.PDFA_3U
  • PDF/A-4 – PdfSpec.PDFA_4 – requires PDF2.0
  • PDF/A-4e – PdfSpec.PDFA_4E – requires PDF2.0

The combining can be done as follows:

    pd4ml.writePDF(os, PdfSpec.PDFA_3B); // implicitly adds PDF1.7 conformance
    pd4ml.writePDF(os, PdfSpec.PDF_1_7_8.combine(PdfSpec.PDFA_3B));

And also PDF or PDF/A-a can be combined with PDF/UA

  • PDF/UA-1 – PdfSpec.PDFUA_1
  • PDF/UA-2 – PdfSpec.PDFUA_2 – requires PDF2.0

Examples:

    pd4ml.writePDF(os, PdfSpec.PDFUA_1); // implicitly adds PDF1.7 conformance
    pd4ml.writePDF(os, PdfSpec.PDF_1_7_8.combine(PdfSpec.PDFUA_1));
    pd4ml.writePDF(os, PdfSpec.PDF_1_7_11.combine(PdfSpec.PDFA_3A).combine(PdfSpec.PDFUA_1));

There are also several predefined constants that combine PDF standards as required by XML invoicing specs:

  • ZUGFeRD – PdfSpec.ZUGFeRD, which is PdfSpec.PDF_1_7.combine(PdfSpec.PDFA_3B)
  • ZUGFeRD (tagged) – PdfSpec.ZUGFeRD_a, which is PdfSpec.PDF_1_7.combine(PdfSpec.PDFA_3A)
  • Factur-X – PdfSpec.FacturX, which is PdfSpec.PDF_1_7.combine(PdfSpec.PDFA_3B)
  • Factur-X (tagged) – PdfSpec.FacturX_a, which is PdfSpec.PDF_1_7.combine(PdfSpec.PDFA_3A)


NOTE: Not all the standards can be combined with each other. PdfSpec.combine() throws PdfSpecViolationException and PdfSpecUnsupportedException in incompatibility cases.

ZUGFeRD and Factur-X PDF Invoices generation support


Starting with version v4.1.0, PD4ML DMS and PD4ML UA support PDF/A-3b format and embedding XML invoices into PDF files.

Now, it’s possible to combine both the document’s visual human-readable presentation and its ZUGFeRD/Factur-X XML machine-readable data in a single HTML template. The HTML template can either be completely generated on the fly by the host applicaion, or a static pre-prepared template marked with placeholders can be populated with dynamic data using PD4ML.

Read more: ZUGFeRD and Factur-X PDF Invoices generation

PD4ML Fonts Tool


PD4ML Fonts Tool: glyphs of a font

To simplify the creation of font mapping files, PD4ML v4.0.16 introduces a handy tool. The tool is implemented as an utility of the interactive PD4ML Converter

How to use it

Run the converter, as described by the link /support-topics/pd4ml-v4-programmers-manual/ and click the [Fonts Tool] button on the status bar of the application window.

It will prompt you for the location of the font directory. Select a directory. We can start with system fonts like C:\Windows\Fonts

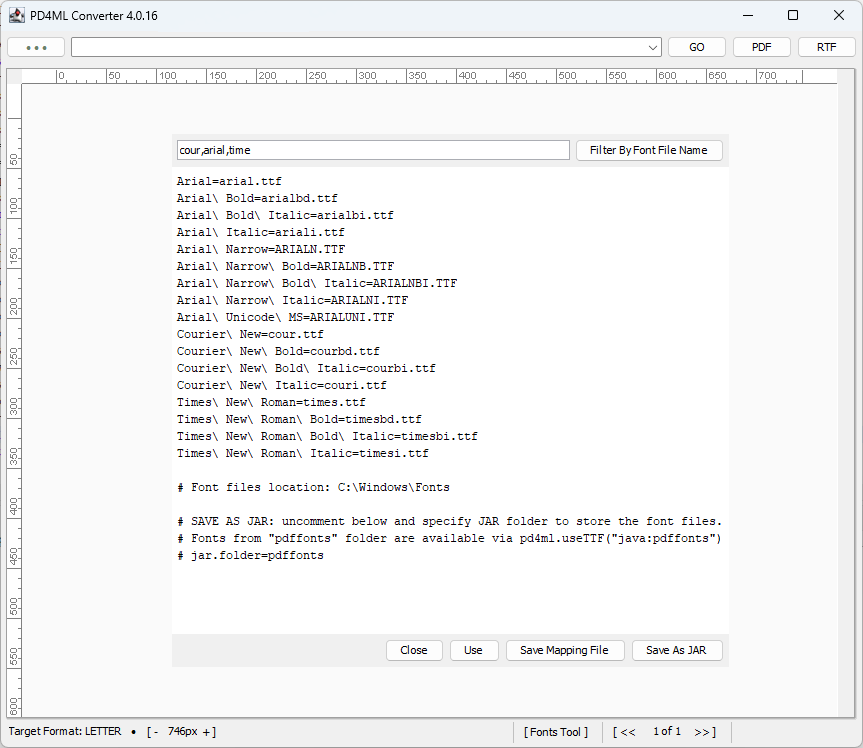
PD4ML Fonts Tool window

Because the system font directory contains an excessive number of fonts that your application doesn’t really need, you can filter them out by entering a comma-separated list of font name patterns in the input field next to the “Filter by Font File Name” button. Apply the filter by pressing the button. The resulting list will include only those fonts whose filenames case-insensitively match the given patterns.

The generated list is editable, so you can manually refine it.

At this point you have four options:

  • Close – is obvious: close the tool and lose the current font mapping configuration
  • Use – use the font configuration only in the current session of the PD4ML Converter, without saving it.
  • Save Mapping File – creates a pd4fonts.properties file that can later be referenced from your application with pd4ml.useTTF() API call. If the chosen mapping file location is different from the original font directory (which is a good idea if you are using the system font directory), pd4fonts.properties will include a link to the font dir, allowing PD4ML to find the actual font files.
  • Save as JAR – packages the listed fonts and the corresponding pd4fonts.properties into a JAR file. Fonts are stored in the “pdffonts” JAR subdirectory by default, so once the JAR is deployed with a PD4ML-enabled application, the font configuration can be referenced with pd4ml.useTTF("java:pdffonts") API call. The subdirectory name can be customized by uncommenting and setting the jar.folder=pdffonts property.